
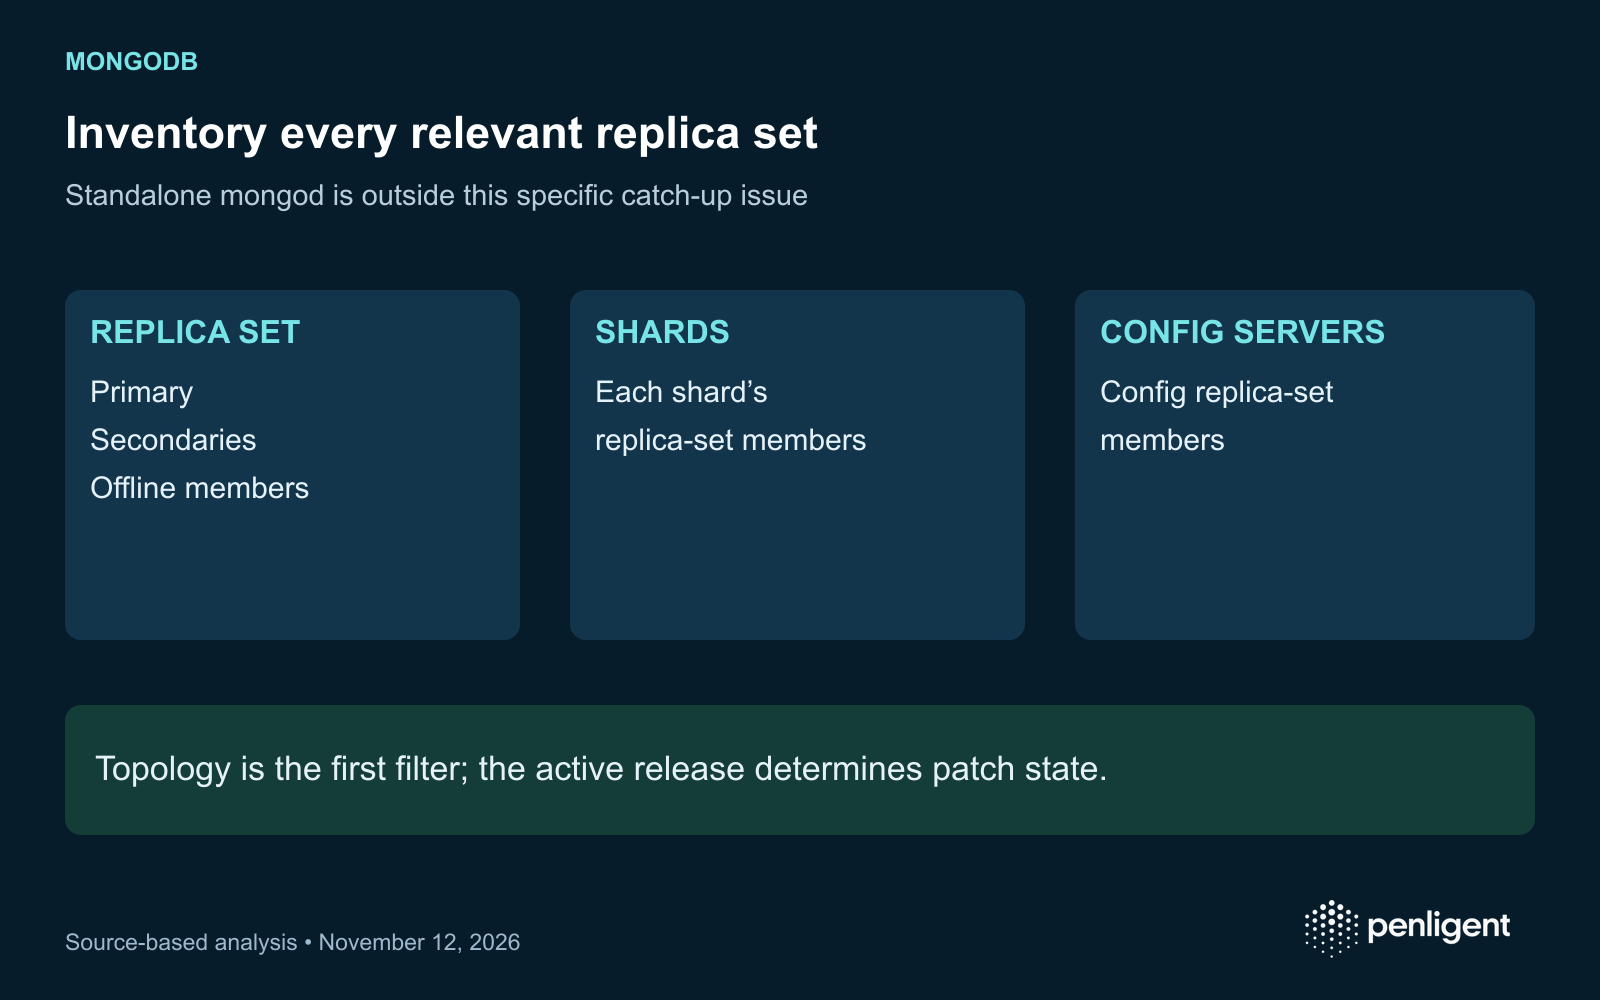
CVE-2026-118383 requires an inventory of MongoDB replica set members, including shard and config-server replica sets. Treat the deployment topology and the running version as separate fields. A patched application container or an enabled database password does not establish that every affected database member is corrected.
Identify the affected topology before scheduling the upgrade
The MongoDB CNA record describes a pre-authentication use-after-free during replica set primary catch-up. Affected members may terminate unexpectedly and, under certain conditions, execute arbitrary code in the server process. Standalone mongod instances are outside this specific replica-set catch-up issue.
MongoDB’s November 10 announcement says the issue was found internally and that it was not aware of exploitation attempts at that time. That is a dated vendor statement. It is not a finding that a particular exposed cluster was never targeted.
Use the branch-specific fixed-release matrix
| MongoDB Server branch | First fixed release in the CNA mapping | Operational check |
|---|---|---|
| 9.0 | 9.0.7 | Verify every serving member in the branch. |
| 8.3 | 8.3.16 | Include members deployed through automation. |
| 8.0 | 8.0.37 | Do not infer the running version from an available image tag. |
| 7.0 | 7.0.48 | Retain the package and process version evidence. |
| 6.0 | 6.0.30 | Confirm support and upgrade path with the provider. |
| 5.0 | 5.0.35 | A fix boundary is not a promise of general lifecycle support. |
| 4.4 | 4.4.32 | Record the supported migration plan separately. |
These are the first fixed releases listed for this CVE, not a recommendation to select an old branch for a new deployment. If using a distributor build, obtain its explicit fix/backport statement and identify the installed package. An image digest, package inventory and active process observation answer different questions; retain enough evidence to connect them.
Do not use authentication as the exposure verdict
Datadog Security Labs’ November 11 research reports a crash reproduced on 8.0.34 and a corrected comparison on 8.0.37. It explains that the issue depends on a member later entering the relevant catch-up state; the researchers created the lag and failover in their lab. Their crash demonstration should not be described as a demonstrated production code-execution exploit or a universal time-to-compromise.
The research also shows why authentication being enabled is not a sufficient negative test for this pre-authentication path. Reduce network access to the systems that need the service while completing upgrades, following vendor guidance. Network restriction reduces reachability; it does not change the vulnerable server code.
Keep Atlas maintenance and self-managed rollout separate
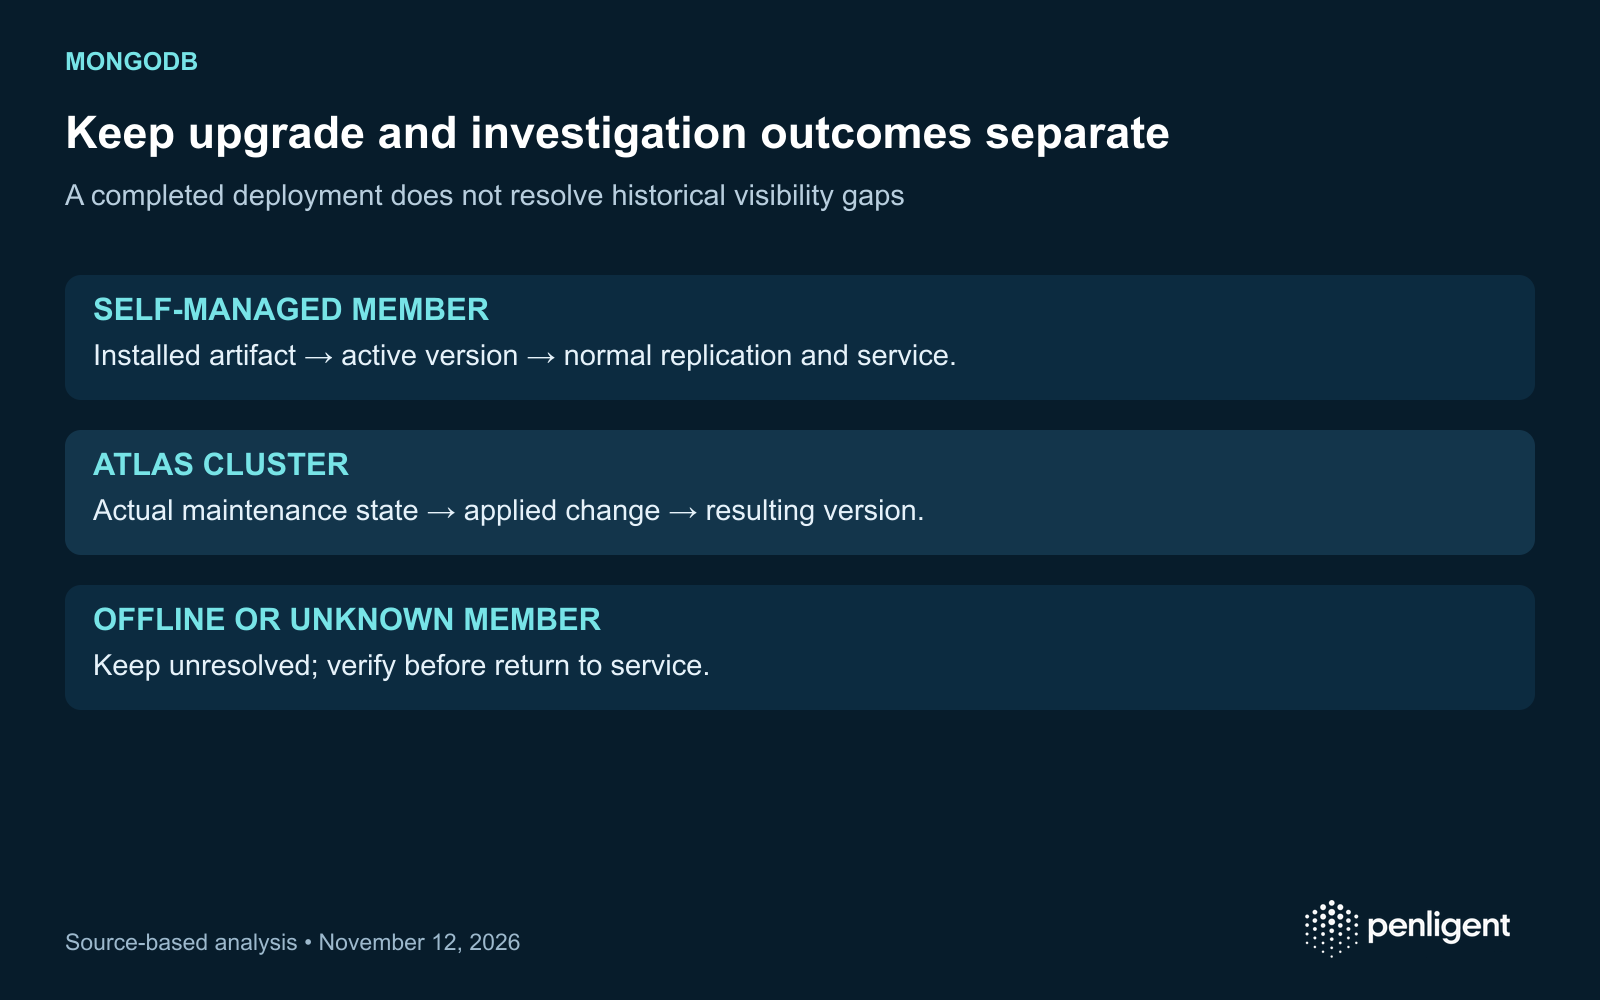
MongoDB says Atlas clusters are upgraded during maintenance and urges customers deferring maintenance to apply the upgrade promptly. Capture the actual cluster maintenance status and resulting version. A provider-managed service does not justify replacing the customer’s maintenance record with an assumption that every cluster has already completed the change.
For self-managed deployments, use the supported upgrade procedure for the topology. Inventory primaries, secondaries, shard members, config-server members and offline nodes that may return. Coordinate availability, backup and rollback planning with the database owner. Do not trigger a production election or send a public crash payload merely to validate that a fix exists.
| Member state | Evidence needed | Disposition |
|---|---|---|
| Active and updated | Host/member identity, runtime version, rollout time and health | Close the version check; retain normal-operation evidence. |
| Offline during maintenance | Last known version, owner and return-to-service control | Keep unresolved until corrected and verified before rejoining. |
| Atlas maintenance deferred | Provider maintenance state, planned application and final version | Track as an outstanding maintenance decision. |
| Version or topology unknown | Inventory source and responsible owner | Classify as inconclusive, not unaffected. |
Close with evidence from each member
Cluster / replica set / member identity
Topology role and deployment owner
Installed artifact → active mongod version
CVE branch mapping or distributor fix statement
Maintenance completion and health observations
Offline members and exceptions
Exposure review scope and telemetry limitations
Retest date and return-to-service condition
Patch closure should show that each relevant member runs a corrected build and the intended database service remains healthy. Incident review is a separate question about historical access and evidence. Keep the two conclusions explicit so a successful upgrade cannot erase a telemetry gap or an unresolved offline member.
Keep database patch closure with the database operator. A separately scoped application assessment with Penligent should define the reachable application behavior and evidence it is intended to evaluate.
The official Penligent 3.0 video below demonstrates the general product workflow. It illustrates product use; the article’s assessment proposals and source findings are evaluated separately.
Method: AI-assisted review of the linked primary sources, checked November 12, 2026, with an original assessment framework. No exploit, production target or customer environment was tested for this article.
 English
 German
 French
 Spanish
 Portuguese
 Japanese
 Korean
 Hindi
 Arabic
 Turkish
 Hebrew