
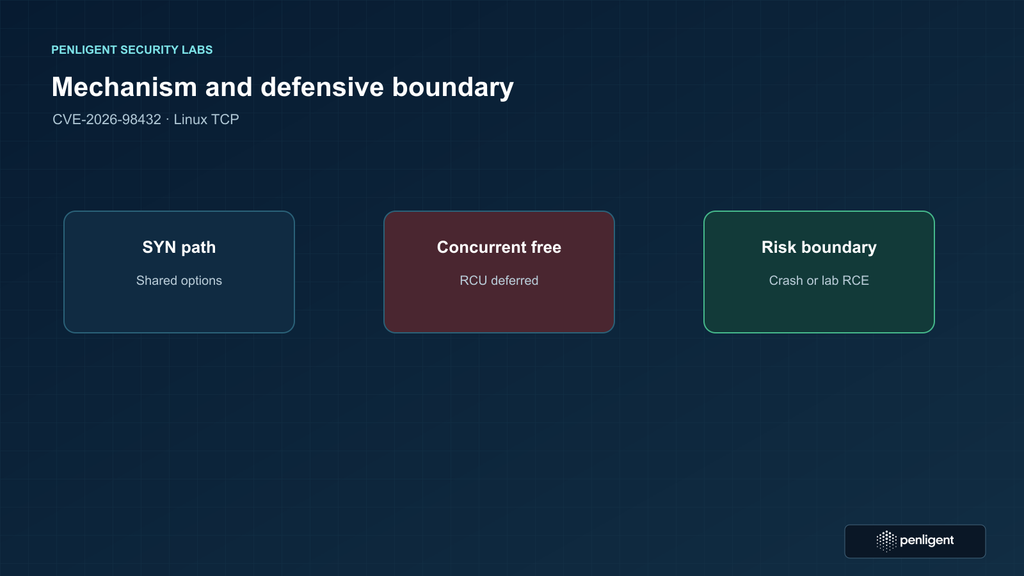
CVE-2026-98432 is a use-after-free in the Linux kernel’s IPv4 TCP handshake path. The flaw appears when two processors act on related request and child sockets while both can still reference the same IP options object. One path may free that object immediately while another path, protected only as an RCU reader, continues to use it. The result is a stale kernel pointer in code reachable through network traffic.
The concise description sounds like a familiar kernel race, but the public evidence demands careful interpretation. The CVE record carries a CVSS 3.1 score of 9.8, representing a network-reachable, unauthenticated worst case with high confidentiality, integrity, and availability impact. Red Hat’s product analysis assigns a lower 5.9 score because it treats exploitation as a difficult race and assesses the practical consequence in its supported products more conservatively. Separately, Anthropic’s Frontier Red Team reported a working remote root code-execution chain against a Linux server with a Multipath TCP listener in a controlled lab. That result is serious evidence of exploitability under a specific configuration. It is not evidence that every unpatched Linux server, every ordinary TCP listener, or every distribution build can be compromised in the same way.
Defenders should treat those statements as complementary. The upstream record identifies a dangerous memory-lifetime error and its theoretical maximum impact. A distribution score describes the vendor’s shipped code, configuration, mitigations, and expected exploit conditions. A research exploit demonstrates one concrete path through a particular target. None of the three should be discarded, and none should be stretched beyond its scope.
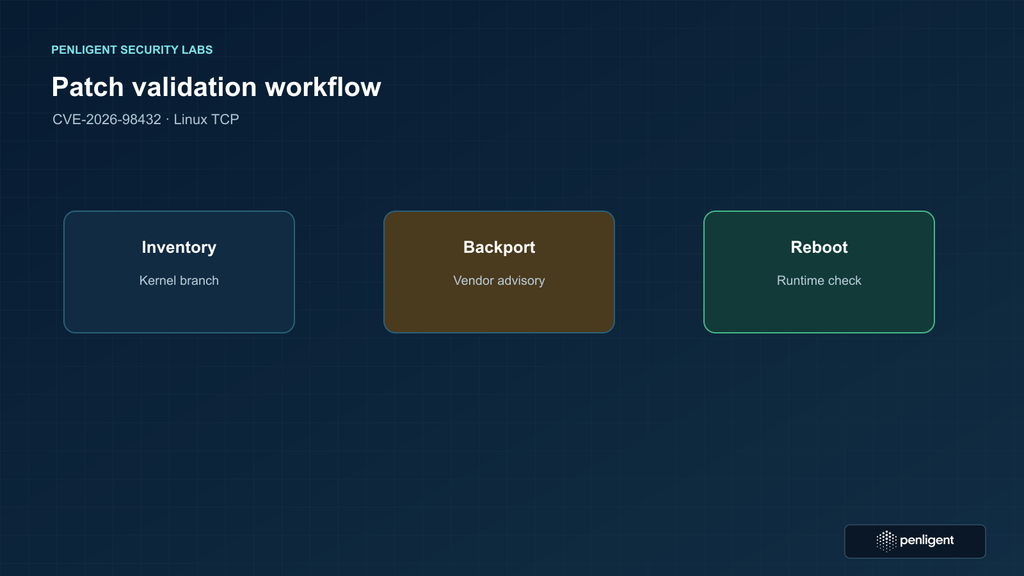
The practical response is direct: identify reachable Linux TCP services, determine which vendor kernel is actually running, install the vendor-provided fixed build, reboot into it, and retain evidence that the running kernel contains the correction. Hosts that expose MPTCP listeners deserve immediate attention because the public research specifically validated that environment. Internet-facing gateways, load balancers, Kubernetes nodes, VPN endpoints, reverse proxies, and appliances that use Linux networking also deserve a fast inventory even if they do not intentionally enable MPTCP.
What is confirmed about CVE-2026-98432
The authoritative technical description comes from the Linux kernel CVE process and the upstream patch. The issue involves ownership and reclamation of IPv4 option data associated with a TCP request socket. During the server side of a TCP handshake, the kernel creates a lightweight request socket to represent a connection that has not yet become a full child socket. When the handshake progresses, tcp_v4_syn_recv_sock() transfers the request’s ireq_opt pointer to the new child socket as inet_opt. It does not duplicate the object.
At the same time, a different CPU can process a retransmitted SYN associated with the same request. That second path can send another SYN-ACK through tcp_check_req(). Functions such as tcp_v4_send_synack() ve inet_csk_route_req() read the request’s IP options inside an RCU read-side critical section. Later helpers, including ip_build_and_send_pkt() ve ip_options_build(), dereference fields from the options object. The Debian security tracker reproduces the upstream explanation and maps the issue to fixed Debian kernel packages.
The lifetime mismatch is the core problem. The reader behaves as though RCU protects the object, but the destructor frees it with ordinary kfree(). Ordinary kfree() makes the allocation available for reuse without waiting for existing RCU readers to finish. If the child socket is destroyed while a retransmitted-SYN path still uses the options, the second CPU can continue reading memory that no longer belongs to that object. The primary upstream fix replaces immediate freeing with kfree_rcu() in the relevant destructors, delaying reclamation until an RCU grace period has elapsed.
The vulnerability also has a related request-migration case. If net.ipv4.tcp_migrate_req=1 is enabled, or if a BPF_SK_REUSEPORT_SELECT_OR_MIGRATE program controls request migration, the kernel may clone a request socket. The old request and its clone can temporarily share the same options object. A CPU holding a reference to the old request can still use the object while the clone is freed. The kernel description therefore changes both inet_sock_destruct() ve tcp_v4_reqsk_destructor() to use RCU-aware reclamation.
The first issue is specific to the IPv4 child-socket path because the corresponding IPv6 function duplicates options instead of transferring the same pointer. The upstream text also notes an IPv6 request-migration concern involving ipv6_opt when CALIPSO is present and says that condition is handled separately. That distinction matters: a statement that “IPv6 is unaffected” is too broad, while a statement that the main IPv4 ownership-transfer bug does not apply to the ordinary IPv6 child creation path is accurate.
The patch was merged upstream as commit e3f33b0a1d89, titled “ipv4: free inet_opt and ireq_opt after an RCU grace period.” The Ubuntu CVE page identifies the same introduction and fix commits and tracks many Ubuntu kernel flavors independently. This is useful evidence that a generic kernel version check cannot replace distribution-specific status.
Facts that are not established
No authoritative source cited here establishes widespread exploitation across the public internet. Anthropic established that its researchers could turn the flaw into remote root command execution against a controlled target with an MPTCP listener. That is stronger than a crash-only proof and should influence urgency. It still does not provide a measured prevalence of vulnerable MPTCP services, a universal success rate, or proof that the same exploit chain works unchanged across kernel builds, CPU architectures, allocators, hardening profiles, and network paths.
The public material also does not justify assuming that any high volume of SYN retransmissions is exploitation. Retransmitted SYN packets occur naturally because of packet loss, asymmetric routing, overloaded services, client retry behavior, and middleboxes. Exploitation of a race may generate unusual patterns, but those patterns need correlation with a vulnerable host, relevant options, kernel symptoms, and timing. A network alert can prioritize investigation; it cannot prove a use-after-free occurred inside the kernel.
There is no single upstream version string that accurately labels every vendor kernel. Enterprise distributions routinely backport security fixes while retaining an older-looking base version. Cloud providers and appliance vendors may ship their own kernel builds. A scanner that compares only uname -r against an upstream release list can produce both false positives and false negatives. The defensible conclusion comes from a vendor advisory, package changelog, build metadata, VEX statement, or direct confirmation that the relevant fix commit was backported.
Finally, disabling MPTCP does not remove the underlying IPv4 lifetime bug. It removes the exact listener configuration used in the public research chain and can meaningfully reduce immediate exposure where MPTCP is unnecessary. The upstream technical description covers the ordinary IPv4 TCP request and child socket paths as well as request migration. Patch deployment remains the durable correction.
How the vulnerable TCP path works
A TCP server normally receives a SYN, replies with SYN-ACK, and waits for the final ACK. The kernel avoids allocating a complete connected socket at the first packet because an attacker could otherwise exhaust resources cheaply. Instead, it creates a compact request socket that stores enough state to validate and complete the handshake. When the ACK arrives and the connection is accepted, the kernel creates a full child socket and moves or copies selected state into it.
IPv4 options complicate that transition. IP options can carry metadata that influences routing or packet processing. The kernel parses the incoming information and stores an internal representation for later response construction. In the affected path, the request socket’s ireq_opt pointer becomes the child socket’s inet_opt pointer. The transfer avoids a copy, but it means the lifetime of one allocation crosses the boundary between two socket objects.
A second SYN for the same connection tuple can arrive before the handshake state has completely settled. Retransmission is a normal part of TCP. The kernel may process that SYN on another CPU and build a SYN-ACK using the original request socket. Since Linux networking is highly parallel, the child socket can progress toward teardown while the other CPU is still constructing the reply. The request path takes an RCU read lock, indicating that the data it reads must remain valid until the read-side critical section ends.
The old destructor behavior violated that expectation. The child socket did not carry the SOCK_RCU_FREE behavior that would defer its entire release, and inet_sock_destruct() freed inet_opt directly. The second CPU could retain the pointer and read optlen from memory that had already returned to the allocator. A later allocation could place unrelated data at that address, changing the value between reads or letting subsequent code operate on attacker-influenced contents.
Use-after-free bugs are dangerous because the immediate symptom depends on what replaces the freed allocation. The stale access may read the old bytes and appear harmless. It may encounter poisoned or unmapped memory and crash. It may read a new kernel object and disclose data. With sufficient control over allocation patterns and timing, a researcher may turn the stale reference into a more powerful read, write, or control-flow primitive. The vulnerability class therefore supports outcomes ranging from intermittent handshake failure through denial of service to code execution, but a specific outcome must be demonstrated for a specific target.
The request-migration variant follows the same lifetime principle through a different topology. Reuseport allows multiple sockets to share a listening port, and BPF can participate in choosing a target. Request migration may move pending connections when a listener changes state. The kernel clones request state, creating a window in which two request objects refer to the same options allocation. Clearing the pointer in one object does not protect a CPU that already holds a reference to it. If the other object’s destructor immediately frees the shared allocation, that reader becomes stale.
The patch does not attempt to serialize every operation behind one global lock. That would harm scalability in a hot network path. It instead aligns reclamation with the synchronization model that readers already use. This is precisely the kind of problem Read-Copy Update is designed to solve.
Why RCU changes the safety boundary
Read-Copy Update lets readers access shared data with very low overhead while writers publish replacements and defer freeing old versions. A reader enters an RCU read-side critical section, obtains a pointer, uses the object, and exits. A writer can remove the object from the data structure so new readers no longer find it, but it must wait for a grace period before reclaiming memory. A grace period ensures that all readers that could have seen the old pointer have finished.
The Linux kernel’s RCU documentation describes the essential removal-and-reclamation split. Removal changes reachability. Reclamation returns storage to the allocator. Conflating those operations is a common source of use-after-free errors. An RCU lock does not place a reference count on an arbitrary object and does not make direct kfree() safe. The corresponding writer must use an RCU-aware mechanism such as call_rcu() veya kfree_rcu().
In CVE-2026-98432, the read paths already use RCU. The correction makes the destructor honor that contract. kfree_rcu() schedules the object for release after a grace period rather than releasing it immediately. The CPU building the SYN-ACK can finish reading the old options object. Later readers will no longer obtain it, and the allocation becomes reusable only after the preexisting readers are gone.
This design preserves concurrency. It does not require the server to stop processing retransmissions, place a large lock around handshake construction, or copy the options object for every read. The security property is narrow and clear: an object visible to an RCU reader remains allocated for the duration in which that reader might access it.
RCU fixes also explain why packet filtering alone cannot be a complete remedy. The memory-safety defect is in object lifetime management. Filtering may make a trigger harder to reach, and disabling unneeded features can reduce the set of paths. Only corrected reclamation restores the invariant for every legitimate and hostile packet that reaches the code.
Reconciling the 9.8 and 5.9 scores
The CVE record’s CVSS 3.1 vector is AV:N/AC:L/PR:N/UI:N/S:U/C:H/I:H/A:H, producing 9.8. This vector assumes a network attacker needs no account and no user interaction, that attack complexity is low, and that successful exploitation can have high impact across confidentiality, integrity, and availability. It expresses the CNA’s base characterization of the vulnerable upstream component.
Ubuntu displays that 9.8 value but also publishes a CVSS 4.0 assessment of 8.3 with attack requirements present. CVSS 4.0 can represent prerequisites that do not fit cleanly into the older vector. Ubuntu’s page labels the vulnerability high priority and exposes package-by-package states rather than treating the numeric score as the entire decision.
Red Hat’s 5.9 score reflects a different assessment. Red Hat evaluates vulnerabilities in the context of its products, backports, default configurations, mitigations, and likely consequences. Its analysis treats the race as high complexity and emphasizes that a reliable security impact may be a crash or denial of service, while memory corruption and stronger outcomes depend on additional conditions. A lower vendor score does not mean the upstream bug is imaginary; it means the vendor does not accept every worst-case metric for the products it ships.
CVSS disagreement is common for open-source components distributed in different forms. The same source defect may be present in two products but exposed through different configurations. One vendor may enable a feature by default, another may omit it, and a third may carry a partial backport that changes reachability. Kernel hardening, allocator behavior, architecture, compiler options, and service topology can all affect exploit development without changing the vulnerable source line.
For operational prioritization, a single universal score is less useful than a short environment-specific analysis:
| Environment factor | Why it changes urgency | Defender action |
|---|---|---|
| Publicly reachable TCP service | Untrusted users can exercise handshake paths without an account | Patch in the earliest emergency window |
| MPTCP listener enabled | The public research demonstrated remote root execution in this configuration | Patch immediately and disable MPTCP if unused |
| Management-only host behind strong filtering | Network access is constrained but insider and lateral paths remain | Patch quickly through normal change control |
| Request migration or reuseport BPF | The upstream description identifies a related shared-object path | Inventory the configuration and prioritize affected listeners |
| Vendor marks installed build fixed | The relevant correction may be backported despite an old base version | Verify the running build and retain vendor evidence |
| Unsupported kernel | No reliable security update or vendor analysis may arrive | Upgrade to a supported kernel or isolate the host |
The 9.8 score is useful for recognizing the potential ceiling. The 5.9 score is useful for understanding Red Hat’s product-specific view. Neither number should override the fact that an exposed MPTCP target was exploited in a lab, and the lab result should not be converted into a claim of mass exploitation. Defenders can act urgently while preserving those distinctions.
What the Anthropic MPTCP research proves
Anthropic’s October 27 research post describes a remote, zero-click Linux kernel exploit against a server with a Multipath TCP listener. According to the researchers, the exploit used the race-induced use-after-free in two stages. The first stage obtained a kernel pointer and defeated Kernel Address Space Layout Randomization. The second stage converted the memory corruption into control-flow hijacking and ultimately ran an attacker-chosen command as root.
The team reports that its proof of concept took approximately 48 minutes to disclose a kernel pointer and another five minutes to reach command execution. A failed attempt could leave the handshake incomplete without necessarily crashing the host, allowing repeated trials. That behavior is relevant because race-condition exploits often become practical when failure is cheap and retries are plentiful.
The research is credible evidence that the vulnerability can exceed denial of service. It also tells defenders which public exposure deserves the highest priority: untrusted network access to an MPTCP-enabled listener on a vulnerable kernel. The official Linux MPTCP documentation explains how Multipath TCP extends ordinary TCP so a connection can use multiple subflows while remaining compatible with existing applications. Linux distributions may provide MPTCP support without every application or service using it, so administrators need to check runtime state and listeners rather than infer exposure from package presence.
The published summary is not a reusable exploit recipe. It omits the target-specific details required to reproduce heap state, timing, address disclosure, and reliable control. Responsible defense does not require reproducing those stages on production systems. The existence of a working research chain, coordinated disclosure, upstream correction, and stable backports supplies enough evidence to patch.
Several boundaries should remain explicit. The research target used MPTCP. Kernel builds differ. The reported time is one experimental result, not a guaranteed minimum or maximum. Network latency, CPU count, load, allocator behavior, hardening, and service implementation can change the race. The post does not say that an ordinary TCP service with default settings on every distribution is equivalently exploitable.
The most defensible wording is therefore: CVE-2026-98432 is remotely reachable through Linux networking; Anthropic demonstrated unauthenticated root code execution against a vulnerable MPTCP listener in a controlled environment; broader exploitability and reliability depend on the target. This statement preserves both urgency and accuracy.
Affected versions and vendor backports
The vulnerable behavior was introduced by older upstream changes, including commit 079096f103fa, which allowed TCP and DCCP request sockets to be installed in the established hash table without the listener lock, and another change associated with request migration. Because the affected history spans many maintained branches, the Linux CVE record enumerates branch-specific fixes rather than one simple vulnerable range.
Upstream stable fixes were issued across maintained lines. The first corrected releases identified in the public record include 5.10.272, 5.15.223, 6.1.190, 6.6.159, 6.12.113, 6.18.56, 7.2.10, and the 7.3 development line containing the mainline fix. These numbers are useful for upstream kernels. They must not be used as a universal rule for vendor packages because vendors may backport the correction to builds with lower base numbers or maintain a branch with additional revision identifiers.
Debian’s tracker, for example, marks Bookworm’s 6.1.190-1 security package and Trixie’s 6.12.113-1 package fixed. It also records fixed builds in later suites. Those package versions are the correct evidence for Debian systems. On Ubuntu, the security page lists many separate kernel source packages, including generic, AWS, Azure, GCP, KVM, Oracle, OEM, low-latency, and real-time variants. A status for one flavor does not automatically prove another flavor is fixed.
Red Hat customers should use the Red Hat CVE page and errata applicable to the exact RHEL or OpenShift product. Enterprise kernels deliberately retain stable interfaces and version families while incorporating security patches. A version-only scanner that expects the upstream first-fixed version may flag a corrected Red Hat kernel. Conversely, seeing a high base version in an appliance does not prove the vendor included every stable patch.
Bu SUSE CVE page, Gentoo security advisories, cloud-provider notices, and appliance vendor bulletins should be consulted for their respective products. When a vendor has not published a determination, administrators can ask for a VEX or support statement identifying whether the vulnerable code is present and which build includes the fix.
Containers deserve special attention. Containers normally share the host kernel. Updating an application image does not replace the kernel that handles its TCP traffic. Managed Kubernetes customers may need a node-image update, a node-pool rollout, or a provider maintenance action. Self-managed clusters need host package updates and node reboots. After replacement, verify every node rather than assume the control plane rollout reached the entire fleet.
Live patching may or may not cover this change. The correction affects object reclamation in network destructors, and coverage depends on the vendor’s live-patch implementation and support decision. Treat a live-patch status as valid only when the vendor explicitly associates it with CVE-2026-98432. If no such confirmation exists, install the fixed kernel and reboot.
Build an exposure inventory before the change window
A good inventory separates vulnerability presence from attack reachability. Presence asks whether the running kernel contains the affected code without the correction. Reachability asks which untrusted networks and services can exercise the relevant handshake paths. Both matter. A vulnerable but isolated lab host can follow a planned update window, while a public MPTCP service should move to the front of the queue.
Start with systems that terminate TCP directly on Linux: reverse proxies, web servers, API gateways, ingress nodes, VPN concentrators, load balancers, mail gateways, DNS-over-TCP services, SSH bastions, database endpoints, and custom daemons. Include appliances if their vendor identifies Linux internally. A hardware-looking edge product can still expose a Linux network stack.
Determine whether a separate device terminates the external connection. A cloud load balancer may absorb the public handshake and establish a second connection to a backend. That can reduce direct reachability of the backend kernel from the internet, but the load balancer itself and any internal untrusted clients remain in scope. Preserve the actual connection path in the asset record instead of relying on application architecture diagrams that omit network termination.
Check MPTCP status. On systems with an appropriate iproute2 version, ip mptcp endpoint show ve ip mptcp limits show can display configured endpoints and limits. Inspect sysctl net.mptcp.enabled where available. Also identify applications that deliberately create MPTCP sockets; a global enable flag alone does not prove a listener exists. The MPTCP upstream project documentation provides testing and deployment references.
Inspect request-migration settings with sysctl net.ipv4.tcp_migrate_req. The default and availability can vary with kernel and configuration. A value of one increases relevance of the migration path described upstream. Identify reuseport BPF programs attached to listening groups. The kernel’s SK_REUSEPORT BPF documentation explains the program type and socket selection context. Absence of these features does not prove the primary IPv4 path is safe, but presence helps prioritize testing and rollout.
Record the effective kernel, package, booted image, architecture, and vendor. For immutable systems, record the node image or operating-system release. For appliances, record the firmware. For managed services, capture the provider advisory or support case. This evidence is more useful than a spreadsheet cell that only says “Linux.”
Map trust boundaries. A service reachable only from a corporate VLAN may still be reachable by compromised laptops, workloads, or partners. Kubernetes node ports can expose listeners in ways that differ from ingress configuration. IPv4 exposure remains relevant even in organizations that prefer IPv6, because dual-stack services and management networks often keep IPv4 enabled.
Safe validation without exploit traffic
Production validation should answer four questions: what kernel is running, what vendor package supplied it, whether relevant services are reachable, and whether the vendor says that exact build is fixed. It should not attempt to win the race, corrupt kernel memory, disclose addresses, or run commands through a proof of concept.
The following commands collect local facts on a system you administer. They do not trigger the vulnerability:
uname -a
uname -r
cat /etc/os-release

# Debian and Ubuntu package evidence
dpkg-query -W 'linux-image*' 2>/dev/null | sed -n '1,40p'

# RHEL-family package evidence
rpm -q kernel kernel-core 2>/dev/null

# Listening TCP sockets
ss -lntp

# MPTCP state when supported
sysctl net.mptcp.enabled 2>/dev/null
ip mptcp endpoint show 2>/dev/null
ip mptcp limits show 2>/dev/null

# Request migration setting when present
sysctl net.ipv4.tcp_migrate_req 2>/dev/null
Run commands with the least privilege needed. Process names in ss output may require elevated permission, but listener addresses and ports are still useful without them. Do not paste full command output into a public ticket if it contains hostnames, internal addresses, or service details.
Next, compare the installed package with the distribution’s advisory. On Debian, use the Debian tracker and the installed source-package version. On Ubuntu, select the exact kernel flavor and release row. On Red Hat, use the applicable product state and erratum. If the vendor says a build is fixed through a backport, accept that mapping over a generic upstream comparison.
Confirm that the system booted the updated kernel. Package installation can succeed while the running kernel remains old. Compare uname -r with the expected installed image after reboot. On systems with multiple boot entries, verify the bootloader selected the correct image. In a cluster, collect the result from every node.
For externally reachable services, validate exposure from an authorized assessment host using ordinary connection attempts, load-balancer configuration, firewall policy, and service discovery. There is no need to transmit malformed IP options or repeated race-triggering handshakes. Standard TCP connectivity is enough to establish that untrusted traffic reaches the host.
If a lab team needs deeper assurance, build a disposable environment using the same vendor image, enable kernel sanitizers only in that environment, and run vendor-approved regression tests. KASAN documentation describes the kernel’s memory-error detector. KASAN is valuable for development and confirmation, but its performance cost and altered memory layout make it unsuitable as a production mitigation and can change exploit timing.
A safe validation report should contain the asset identifier, business service, network exposure, MPTCP state, request-migration state if relevant, package version, running kernel, vendor advisory URL, update timestamp, reboot evidence, service-health result, and any temporary exception. That record supports incident response, audit, and later rescanning.
Detection and incident response
Memory-corruption exploitation rarely produces one definitive log line. Detection should combine kernel telemetry, network behavior, host state, and the known vulnerable build. A kernel crash with a stack near ip_options_build(), ip_build_and_send_pkt(), TCP SYN-ACK construction, or socket destruction deserves immediate review. KASAN reports that identify a use-after-free involving inet_opt veya ireq_opt are especially relevant in test or debug environments.
Review journalctl -k, dmesg archives, crash dumps, and platform serial-console logs. Cloud instances may reboot before local logs are flushed, so centralized kernel logs and provider console history matter. If kdump is deployed, preserve the vmcore, matching unstripped kernel symbols, package metadata, and boot configuration. Do not immediately recycle an affected node if evidence collection is part of the incident plan.
Network telemetry can identify clients that send repeated connection attempts with unusual option combinations or sustain retries against an MPTCP listener. Baseline first. Mobile networks, lossy links, health checks, and SYN proxies can generate high retransmission counts. An alert should include destination service, source distribution, TCP option summary, rate, duration, and whether the target was vulnerable at the time.
An exploit described by Anthropic needed repeated opportunities over a long interval. Long-lived patterns from a single source or coordinated sources may therefore be more interesting than a small burst. Attackers can distribute retries, and normal clients can also retry for extended periods. Treat the pattern as investigative context rather than a signature.
Endpoint detection agents have limited visibility into an exploit that begins and executes inside the kernel. A successful control-flow hijack might later create a user-space process or alter credentials, but it may also perform actions that blend into normal privileged activity. Correlate unexpected root processes, changes to startup configuration, new network connections, module activity, audit events, and integrity-monitoring alerts with kernel and network evidence.
If exploitation is suspected, isolate the host through network controls that preserve evidence, capture volatile state according to the organization’s incident process, rotate credentials that the host could access, and investigate adjacent systems. A kernel-level compromise invalidates assumptions about user-space logs and agent integrity. Rebuild from a trusted image after evidence collection rather than treating a package update as remediation for an already compromised machine.
Check whether the system exposed MPTCP and whether the suspicious source could reach it. Preserve firewall, load-balancer, flow, packet-capture, and service configuration around the event time. Record the exact booted kernel and package before changing it. If the only symptom is a crash, retain the possibility of accidental trigger or an unrelated bug while still patching promptly.
Patch and mitigation strategy
The preferred remediation is a vendor kernel containing the RCU reclamation fix, followed by a reboot into that kernel. Use the distribution’s normal update mechanism and its advisory. Avoid cherry-picking a single mainline commit into an enterprise kernel unless the kernel vendor or an experienced kernel engineering team owns the resulting build. Stable branches may require related context, and unsupported custom kernels create future patch and support risk.
For a fleet, rank systems by public reachability, MPTCP usage, request migration, business criticality, tenant exposure, and vendor support. Begin with internet-facing nodes and infrastructure that terminates large volumes of untrusted TCP. Patch redundant members in a rolling sequence: drain connections, update, reboot, verify the running kernel, perform service checks, and return the node to rotation before continuing.
Where immediate reboot is impossible, reduce exposure. Disable MPTCP if the organization does not use it. Restrict inbound TCP to required sources and ports. Move management services behind authenticated gateways. Remove unused public listeners. Apply rate controls or SYN proxying at an upstream device where operationally safe. These measures can reduce opportunities and protect the specific public-research path, but they do not correct the stale pointer.
Evaluate net.ipv4.tcp_migrate_req and reuseport BPF only with the service owner. Turning off request migration may reduce one affected path but can change failover behavior. Removing a BPF program may change traffic distribution. Configuration changes need functional testing and a rollback plan.
Blocking all IPv4 options at an edge may reduce exposure to paths that rely on option data, but it is an incomplete and potentially disruptive control. Some networks use options for specialized behavior, and the precise relationship between a filter and every vulnerable path must be established. Middleboxes can normalize or terminate connections in ways that differ from simple packet filtering. Use such controls as temporary risk reduction only.
Do not rely on container restarts, application redeployments, or user-space library updates. The vulnerable code runs in the host kernel. Do not assume that a web application firewall sees or understands the relevant IP and TCP handshake state. A WAF that begins processing after a TCP connection is established is downstream of the vulnerable operation.
Unsupported kernels present a straightforward decision. Move the workload to a supported build or isolate it until replacement. A locally patched kernel can be appropriate for specialized products, but it requires owners who can validate the backport, test networking behavior, maintain symbols, publish provenance, and deliver future fixes. For most organizations, moving to a vendor-supported kernel is safer and faster.
Penligent can support authorized validation by helping security teams organize exposed-service discovery, configuration evidence, and retesting around a controlled patch window. The goal for this kernel issue is not to reproduce a remote root chain on production. It is to prove which assets were reachable, which vendor fix they received, and whether the service remained healthy after the corrected kernel booted.
Verify that remediation actually worked
A successful update job is not the same as a remediated host. Verification begins after reboot. Confirm the active kernel with uname -r and map it to the vendor’s fixed package. Confirm the update installed on the expected boot partition and that the bootloader did not fall back after an error. Check that secure-boot policy accepted the image where applicable.
Validate the service from both sides of its trust boundary. An internal health check may pass while the public listener is absent, and a public check may pass while a private backend path is broken. Exercise normal TCP connection establishment, TLS negotiation, protocol health, and representative requests. For MPTCP services, use the organization’s normal MPTCP functional test without hostile timing or memory-corruption attempts.
Review kernel logs for warnings introduced by the rollout. Network fixes can interact with drivers, offload, BPF, load balancing, and custom modules. A regression does not justify returning indefinitely to a vulnerable kernel. Follow the vendor’s rollback or replacement guidance, apply temporary exposure reduction, and escalate for a corrected package.
Rescan with a tool that understands vendor backports. If the scanner still flags the asset, attach the vendor advisory, installed package version, running-kernel evidence, and fix provenance. Suppress only the exact finding for the exact build, with an expiration or review date. Broad exceptions based on an upstream version comparison can hide later vulnerable nodes.
For Kubernetes and autoscaling fleets, verify templates as well as current instances. An old machine image can recreate vulnerable nodes after the initial rollout. Update launch templates, node images, golden images, recovery media, and disaster-recovery definitions. Test a scale-out event and confirm the new node boots a fixed kernel.
For appliances, confirm that the firmware upgrade changed the relevant kernel build. Keep the vendor bulletin and firmware checksum. If the appliance vendor has not published a fix, document compensating controls and obtain a support statement. Avoid assuming that a firmware release date after the upstream patch automatically includes it.
Close the remediation item only when all of the following are true:
- The asset and its real TCP exposure are recorded.
- The vendor identifies the installed build as fixed or not affected.
- The fixed kernel is running, not merely installed.
- The required reboot or vendor-approved live-patch activation completed.
- Critical services passed post-change tests.
- Images, templates, and replacement-node sources were updated.
- Temporary mitigations and exceptions have owners and expiration dates.
- Evidence is retained for incident response and audit.
Common assessment mistakes
The first mistake is treating “Linux” as one product. The kernel is shipped through distributions, cloud images, embedded firmware, managed node images, and custom builds. Each may carry different backports. Use the exact product channel.
The second mistake is equating a CVSS score with exploit prevalence. A 9.8 base score describes technical severity under a metric model. It does not count vulnerable hosts or prove active exploitation. A 5.9 vendor score does not negate a successful lab exploit against another configuration. Risk combines severity, exposure, evidence, asset value, and available controls.
The third mistake is reading the Anthropic result as universal. The research proves that a capable team could exploit a vulnerable MPTCP listener remotely in its lab. It does not establish identical behavior for every TCP listener. Use it to prioritize MPTCP and exposed networking, not to make unsupported claims.
The fourth mistake is declaring IPv6 universally safe. The primary child-socket transfer issue is IPv4-specific, while the upstream description separately calls out an IPv6 migration concern involving CALIPSO. Dual-stack systems also continue to expose IPv4. Evaluate both protocols and follow subsequent vendor fixes.
The fifth mistake is scanning only application containers. Container images do not carry the active host kernel in the normal model. Inventory and patch nodes. Serverless and managed-container customers should consult the provider, because the provider controls the kernel even when customers control images.
The sixth mistake is attempting public exploit code as a production test. Winning the race intentionally can crash or compromise the machine. It also provides little additional business value once the vendor has confirmed that the build is vulnerable. Safe configuration, package, exposure, and post-patch checks provide actionable evidence without weaponizing the flaw.
The seventh mistake is closing the ticket after installation without rebooting. The old kernel remains active until the system boots the new image unless a vendor-supported live-patch mechanism covers the CVE. Always record the runtime result.
Frequently asked questions
Does CVE-2026-98432 allow remote root access on every Linux server?
- No. The bug is network reachable and a controlled research exploit achieved root command execution against a vulnerable MPTCP listener.
- Exploitability depends on kernel build, configuration, architecture, hardening, allocator behavior, service exposure, and race reliability.
- Every affected, reachable host should still be patched because the underlying flaw is kernel memory corruption.
Why does the CVE record say 9.8 while Red Hat says 5.9?
- The CVE score expresses an upstream worst-case base vector with network access, no privileges, no interaction, and high potential impact.
- Red Hat scores the issue for its products and considers the race complexity, shipped configuration, and likely practical outcome.
- Use the vendor assessment for package status and the broader evidence for prioritization.
Is IPv6 affected?
- The main issue in
tcp_v4_syn_recv_sock()is specific to IPv4 because the ordinary IPv6 path duplicates options. - The upstream description identifies a separate IPv6 request-migration concern when CALIPSO options are used.
- Follow the vendor’s complete advisory rather than applying a blanket “IPv6 safe” label.
Does disabling MPTCP fix the vulnerability?
- No. It removes the configuration used by the public remote-code-execution demonstration and can reduce immediate risk if MPTCP is unused.
- The underlying lifetime error also concerns IPv4 TCP request and child socket handling.
- Install the corrected vendor kernel.
Do containers need to be rebuilt?
- The normal container model shares the host kernel, so the node or host must receive the kernel fix.
- Rebuilding an application image alone does not remediate the issue.
- Update node templates and managed-cluster images so autoscaling does not recreate vulnerable hosts.
How should a backported fix be verified?
- Use the distribution’s CVE page, erratum, package changelog, or VEX statement for the exact product and kernel flavor.
- Confirm the fixed package is installed and that
uname -rshows the corresponding running kernel after reboot. - Do not require the upstream first-fixed version when the vendor documents a backport.
Should defenders run an exploit proof of concept?
- Production exploitation tests are unnecessary and can crash or compromise the host.
- Validate kernel provenance, exposure, MPTCP and migration settings, vendor status, reboot completion, and service health.
- Use disposable, authorized lab systems for any memory-safety research.
What evidence suggests an attempted exploit?
- Relevant kernel crashes or sanitizer findings near IPv4 option construction and socket destruction are strong technical clues.
- Repeated unusual handshake attempts against a vulnerable MPTCP listener can increase suspicion but are not proof.
- Correlate network behavior with kernel logs, crash dumps, root-level process anomalies, and the exact vulnerable build.
Final defensive priorities
CVE-2026-98432 is a real kernel object-lifetime failure with a straightforward upstream correction and a demonstrated high-impact research outcome. Its risk should neither be reduced to a theoretical crash nor inflated into a claim that every Linux server is already remotely exploitable. The available evidence supports urgent, targeted action.
Prioritize exposed MPTCP listeners and internet-facing Linux TCP termination points. Use vendor package data rather than generic version matching. Apply the corrected kernel, reboot, validate service operation, update node and appliance templates, and preserve proof of the running fix. Where a change window cannot open immediately, disable unused MPTCP, narrow TCP exposure, and monitor relevant kernel and handshake behavior while scheduling the update.
The most important technical lesson is broader than this CVE: RCU protection is a contract between readers and reclaimers. A reader lock cannot protect an object that a writer returns directly to the allocator. The patch restores that contract by waiting for readers before freeing shared IP options. Verification should restore the operational contract as well: the organization knows which hosts were exposed, which fixed code they run, and whether the service still works after remediation.
Operational notes for MPTCP and dual-stack services
MPTCP inventory is often less obvious than ordinary TCP inventory because administrators may know that the kernel supports the protocol without knowing which application binds an MPTCP socket. Start at the operating-system layer, then ask service owners whether they explicitly create MPTCP sockets or rely on a library or proxy that negotiates subflows. Review service units, container capabilities, socket activation, and deployment configuration. A host-level enabled flag is a clue, not a complete service map. Conversely, an application that can use MPTCP may fall back to ordinary TCP in one environment and actively listen with MPTCP in another.
For each candidate service, document the address families and interfaces where the listener is bound. A listener bound to a wildcard address may be reachable through more interfaces than its service configuration suggests. Host firewall rules, cloud security groups, network policy, and upstream load balancer behavior all contribute. A useful record says whether an untrusted client can complete a path to the host’s TCP stack, whether a proxy terminates the client connection first, and whether internal clients are in scope. This makes it possible to separate a truly isolated service from one that is merely absent from the public DNS zone.
Dual-stack deployments should be assessed as two connected but distinct paths. Inventory IPv4 and IPv6 routes, listeners, security groups, and translation devices independently. The upstream bug’s main ownership transfer is in IPv4 code, but a host with IPv6-only public ingress can still expose IPv4 through a management VLAN, cluster overlay, health-check network, or local peer. An IPv6 packet may also be translated or proxied into a separate IPv4 connection before reaching the vulnerable host. Network architecture, not a product label such as “IPv6-only,” determines what the kernel processes.
Do not disable a protocol across an entire fleet before identifying dependencies. MPTCP may be part of an intentional mobility or path-resilience design. A hasty change can cause throughput loss, break failover, or alter connection behavior in ways that make an incident harder to diagnose. Where MPTCP is not used, disabling it is a sensible temporary reduction in exposure, but record the change and verify that the service has not silently depended on it. Where it is used, prioritize a vendor kernel rollout and apply network restrictions compatible with the service objective.
Plan kernel changes around connection state
Kernel maintenance on network endpoints has an availability dimension. A reboot interrupts established connections, resets connection-tracking state on some appliances, and may change routing or offload behavior. Before updating a load-balanced service, confirm that the remaining healthy nodes have enough capacity. Drain one node at a time, wait for long-lived sessions to close or reach an agreed timeout, update the kernel, reboot, and verify readiness before returning it to rotation. If the service uses MPTCP across multiple paths, include path failover behavior in the change test.
For stateful firewalls and gateways, confirm how the platform handles connection synchronization during rolling maintenance. A node may be healthy at the process level but not ready to accept traffic because routes, tunnel state, or conntrack synchronization has not converged. Include a check from a representative client network, not just a local health endpoint. Keep the previous image available according to the vendor’s supported rollback process, but make sure any rollback triggers the temporary exposure controls described in the risk record.
Coordinate patch windows with kernel extensions and out-of-tree modules. Storage, observability, security, and network agents can prevent a new kernel from booting or can lose functionality after an update. Verify that required modules have compatible builds and signatures. A failed reboot into the old image may leave the host vulnerable while monitoring shows only that the package manager completed successfully. Alert on a mismatch between the expected fixed build and the runtime kernel after maintenance.
In cloud fleets, update the source image before replacing instances. A one-time restart of running virtual machines is insufficient if autoscaling groups, instance templates, recovery plans, or managed node pools still refer to an old image. Test a newly launched replacement in the same network and confirm the vendor kernel is active. For immutable infrastructure, the remediation unit is often the image plus the rollout policy, rather than an individual host package.
For Kubernetes, coordinate node eviction with workload disruption budgets and persistent storage constraints. Update a canary node first, verify CNI and service routing, then proceed across zones. DaemonSets and privileged agents should be checked for kernel-version compatibility. The fact that a container restarts onto a patched node does not prove every replica moved; collect node-level evidence and tie each workload back to its current node. Managed Kubernetes customers should use the provider’s node image and maintenance guidance because the provider owns the kernel build.
Use evidence that survives a later audit
A defensible remediation record ties the advisory to a specific artifact. Save the vendor’s CVE page or erratum, the package name and revision, the host or image identifier, the boot time after the update, and the running kernel string. Where the vendor publishes source-package status, include the exact kernel flavor and release. Where a product bundles a custom kernel, include the appliance firmware version and vendor statement. This prevents a later reviewer from having to infer whether a generic “Linux updated” note covered every system.
For organizations that generate SBOMs, connect the kernel package to the affected asset inventory and preserve a VEX statement when available. A VEX record can say that a product is affected, not affected, fixed, or under investigation, and can explain the basis for that status. It is particularly useful when an upstream CVE database shows a broad affected range while a distribution has backported the change. The statement should remain scoped to the exact product release; do not reuse a determination across a different kernel flavor without evidence.
Keep the original and updated scan results. A before-and-after comparison can show that the scanner recognized a vendor package revision, but it should not replace the vendor mapping. If a scanner continues to report the CVE after an update, record whether the finding is a stale inventory result, an unsupported kernel, a missing reboot, or a false positive due to backport handling. A closed finding with no explanation is difficult to defend and easy to reopen incorrectly.
Track exceptions with an owner, business reason, compensating controls, target date, and explicit re-evaluation condition. An exception for a temporarily unavailable appliance should identify the network paths it can receive, the services exposed, and whether MPTCP is active. Set an expiration rather than making the exception permanent. Reassess sooner if the vendor publishes a fix, new exploit evidence appears, or the appliance’s network boundary changes.
Decision guide for security teams
When the security team receives a CVE alert, the first decision is whether the organization owns a relevant kernel, not whether a vulnerability scanner has already produced a finding. Query endpoint management, cloud inventory, virtual machine images, Kubernetes node pools, network appliances, and embedded product records. Search for the kernel package and supported OS family. A source repository or runtime label can help locate systems, but confirm it against the actual running fleet.
The second decision is which assets can receive untrusted TCP traffic. Use cloud flow logs, load balancer configuration, firewall policy, service maps, and host listeners together. Distinguish direct internet traffic from traffic terminated by a managed proxy. Include trusted internal networks in the threat model because compromised workstations and workloads can become untrusted sources. A control-plane-only appliance may still have a data-plane interface reachable from customer networks.
The third decision is whether any condition elevates the priority. An MPTCP listener, request migration, reuseport BPF, public exposure, high-value network role, or lack of reliable host monitoring should move the system earlier in the queue. These conditions do not prove exploitation. They identify configurations that are closer to the known technical path or have higher business impact if compromised.
The fourth decision is how to validate closure. Identify the supported fixed package, deploy it, restart into it, test network services, and compare the final state against the advisory. Do not accept a planned maintenance ticket or a downloaded package as closure. The runtime state is the evidence that matters. If the patch cannot be applied, record a time-bounded exception and reduce reachable paths while the organization obtains a supported fix.
Finally, decide whether an incident investigation is needed. A vulnerable public MPTCP listener alone warrants urgent patching; it does not by itself prove compromise. Add incident response when there are relevant kernel faults, suspicious long-running connection attempts, unexplained root activity, integrity changes, or credible threat intelligence specific to the affected service. Keeping patch management and incident response linked but distinct avoids both complacency and unsupported breach declarations.
How to communicate the risk accurately
Executive updates should state the affected asset count, reachable service count, MPTCP exposure, fixed-build availability, rollout progress, and unresolved exceptions. Avoid presenting the CVSS 9.8 number without noting the product-specific 5.9 assessment and research conditions. The number is a useful severity signal, but decision-makers need to know what their own environment actually runs and exposes.
A concise technical statement can say: “The Linux IPv4 TCP request path can use IP-options memory after it has been freed. The upstream fix defers reclamation through RCU. Anthropic demonstrated remote root code execution against a vulnerable MPTCP listener in a controlled lab; this does not establish universal exploitability. We are patching internet-facing and MPTCP-enabled systems first and verifying the running vendor kernel after reboot.” This formulation communicates consequence, evidence, boundary, and action without overstating what is known.
Customer-facing communications should follow the organization’s incident and vulnerability disclosure policy. Do not claim a customer system is vulnerable solely because it runs Linux. Ask the platform or vendor for the exact kernel status and state whether a fixed build is available. If service interruption is required for a reboot, communicate the maintenance impact separately from exploit evidence.
Security teams should also preserve uncertainty. If a vendor has not yet assessed a custom image, say that status is under investigation and identify when it will be reviewed. If an MPTCP listener is not found, record the evidence and time of inspection. If the system is patched but a scanner has not recognized the backport, attach the vendor proof and keep the finding in a reviewable state until asset data converges.
 Turkish
 English
 German
 French
 Spanish
 Portuguese
 Japanese
 Korean
 Hindi
 Arabic
 Hebrew